
Decomposed Attention Fusion in MLLMs for Training-free Video Reasoning Segmentation
Abstract
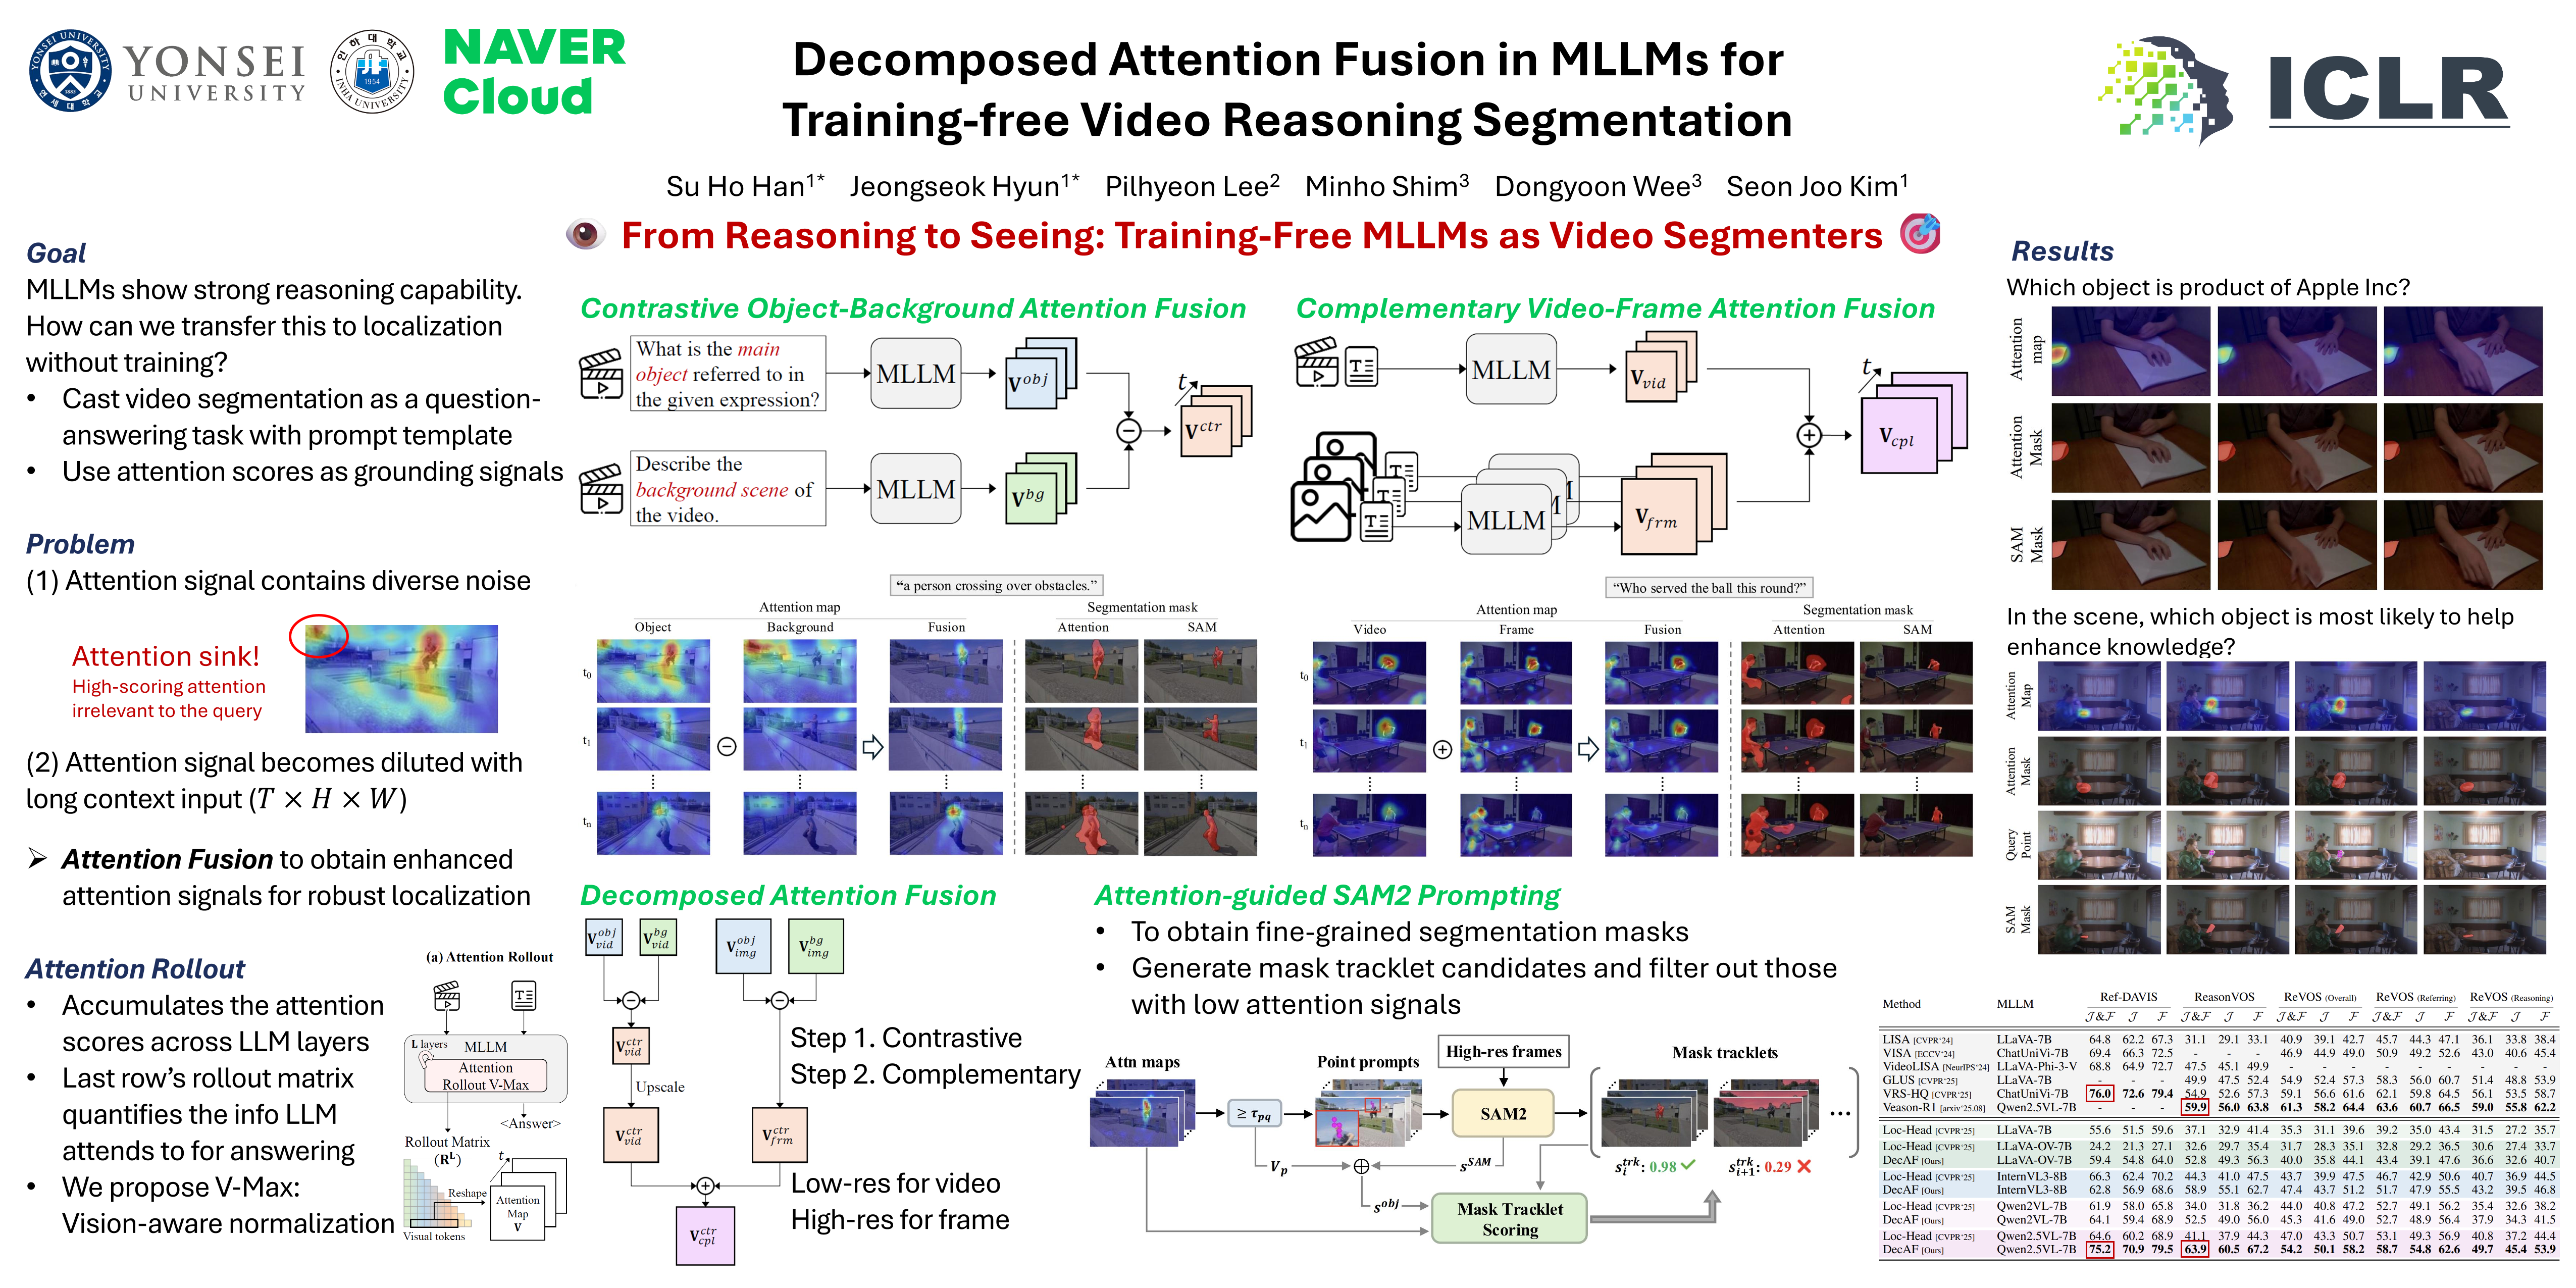
Multimodal large language models (MLLMs) demonstrate strong video understanding by attending to visual tokens relevant to textual queries. To directly adapt this for localization in a training-free manner, we cast video reasoning segmentation as a video QA task and extract attention maps via rollout mechanism. However, raw attention maps are noisy and poorly aligned with object regions. We propose Decomposed Attention Fusion (DecAF), which refines these maps through two mechanisms: (1) contrastive object-background fusion and (2) complementary video-frame fusion. This method suppresses irrelevant activations and enhances object-focused cues, enabling direct conversion of attention maps into coarse segmentation masks. In addition, we introduce attention-guided SAM2 prompting for obtaining fine-grained masks. Unlike existing methods that jointly train MLLMs with SAM, our method operates entirely without retraining. DecAF outperforms training-free methods and achieves performance comparable to training-based methods on both referring and reasoning VOS benchmarks.